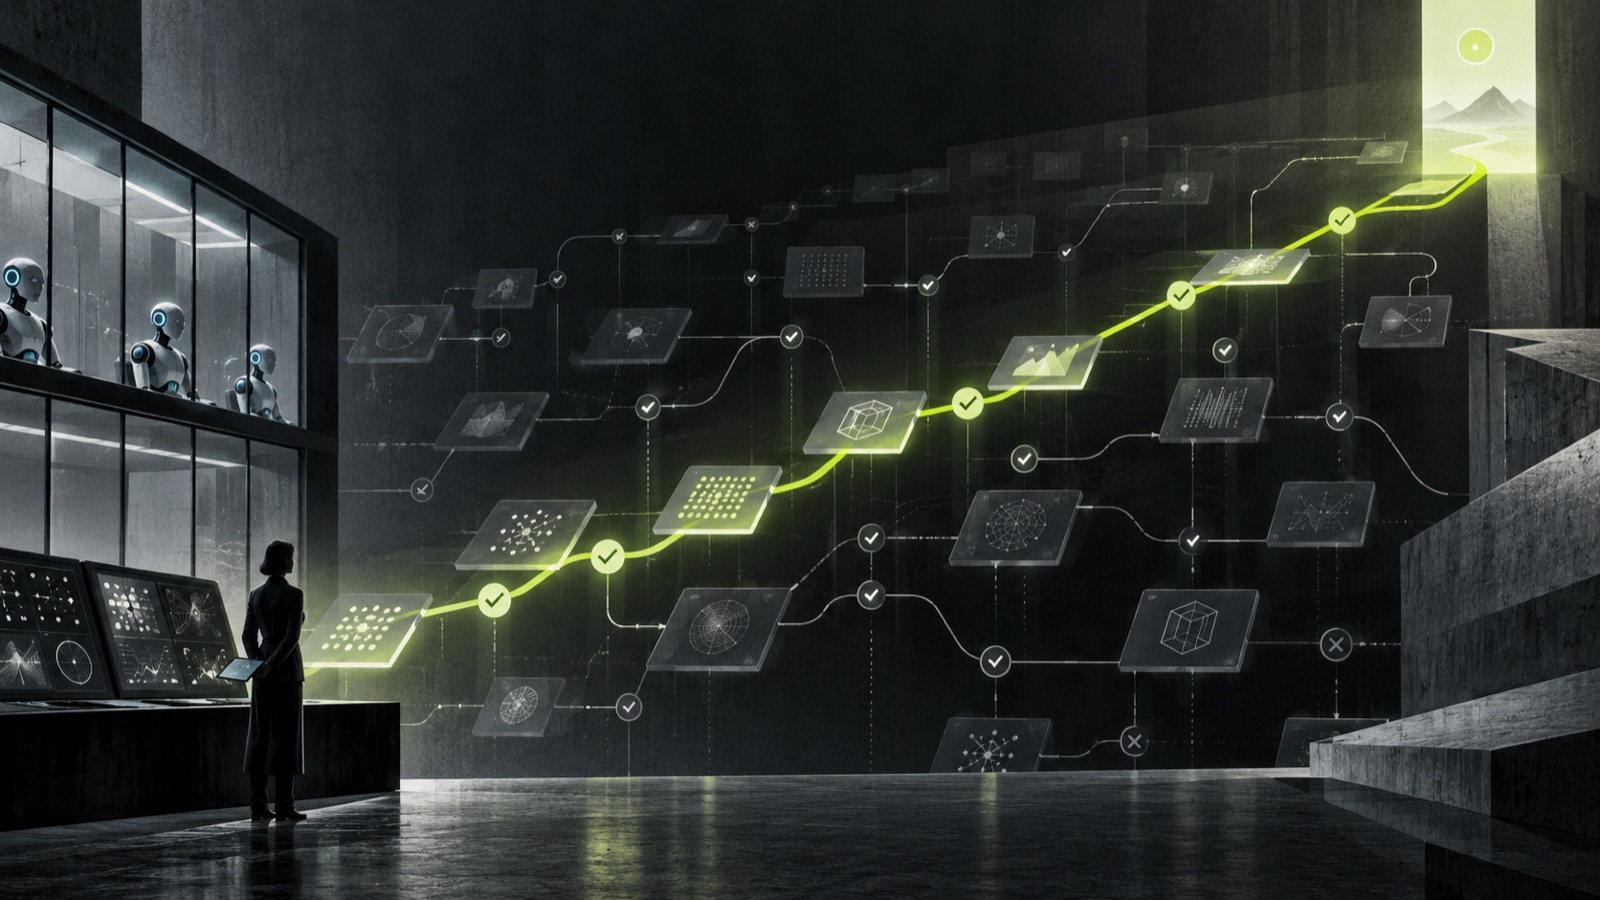
An agent that works in a demo is not necessarily an agent that survives a model update, a changed tool, or a new shape of user request. The durable product is the loop around it: test cases, grading, diagnosis, a change, and another run.
Google's Agents CLI walkthrough makes that loop concrete. It describes commands to generate traces, grade them, compare runs, cluster failures, and optimize a prompt. The example starts with a small dataset and shows how a seemingly harmless prompt change can lower the score.
A score is not a diagnosis
The most useful part of the walkthrough is not the headline score. It is the per-case breakdown. A model swap and a bad system prompt can produce similar averages while failing in completely different places: tool use, scope, tone, or handling a question outside the dataset.
The regression loop is the product feature that keeps the agent honest.
For a small builder, the starting point is a narrow dataset that reflects the real job. Keep the cases in version control, record which model and tools ran, and review proposed prompt improvements for overfitting. Better scores matter only when the agent is better at the work people actually need.
Google's walkthrough describes the Agents CLI evaluation commands and sample project; the reported scores are from that example and are not an independent benchmark.
Google Developers Blog · Hill-Climbing Agent Quality with Agents CLI Evaluation ↗